Checklist OAI 2024 Stage II – Final · Task 3
Self-Supervised Learning (A Classifier in Two Minutes)
Polish title: Klasyfikator w dwie minuty
Pre-train an encoder on unlabelled multichannel sensor time series and fine-tune a classifier on a small labelled subset whose classes differ at test time.
The task
Phones and fitness bands recognise user activity from sensors such as accelerometers, gyroscopes and barometers; such data are multivariate time series. Labelling is expensive, so usually only part of the data is labelled. Self-supervised learning learns representations (latents) without labels, which are then used in downstream tasks such as classification.
The contestant must (1) train a self-supervised encoder on the unlabelled training measurements (train_x_big.pt) and (2) implement finetune_and_predict(X_train_small, y_train_small, X_test, model_path), which trains a classifier on embeddings of the small labelled subset produced by the encoder and returns class indices (not one-hot vectors) for X_test. Inputs have shape (N, 1, 3, 206).
During testing, train_y_small.pt will contain different classes from the supplied file, but the same number of them (for example, {walking, car} during development and {bicycle, swimming} during evaluation). The test set is balanced and comparable to the validation set.
Abridged and translated by SOTA from the official Polish materials. The official statement has the exact rules, and it wins wherever this summary differs.
In English
This task was published in Polish. SOTA translated it into English on 16 September 2026. Only the words changed in the notebooks: markdown, code comments, messages and printed output. The code, file names and paths are the original's, so a translated notebook runs with the original data.
Read the task notebook in English
A classifier in two minutes
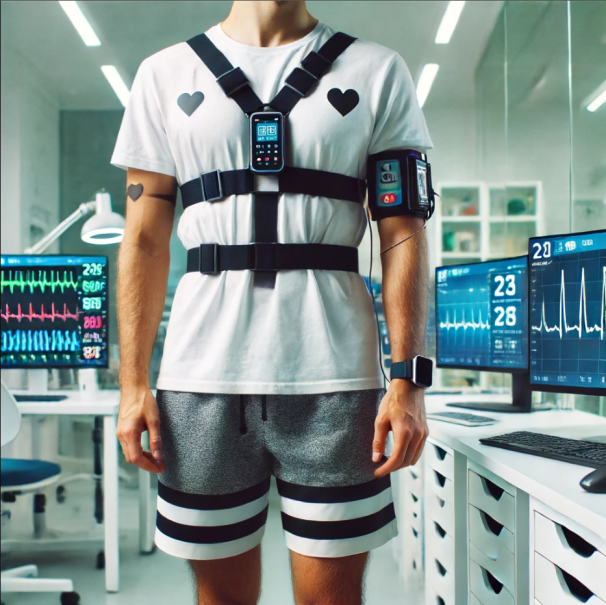
During this olympiad you have had to deal with various types of data, including images and text. But have you ever wondered how phones or fitness bands know what activity you are currently doing?
Your phone contains various sensors, including an accelerometer, a gyroscope and even a barometer. On the basis of the signals from these devices (measured over a certain period), the phone is able to recognise the user's activity.
We call data of this kind (multivariate) time series, because at a given moment we receive data in several dimensions, e.g. from the different axes of the accelerometer.
In practice, labelling data is expensive and requires expert knowledge, which is why usually only part of the data has labels, while labels for the rest of the data are assigned automatically.
Self-supervised learning is a technique that consists of learning representations of data without using their labels. The learned representations, called latent representations (latents), are usually embedded in a lower-dimensional space and represent the input data well. They are later used in so-called downstream tasks, e.g. classification, in which we train a model on the latent representations rather than on the original data.
Files
train_x_big.pt- measurements from the sensors; they are to serve as the training set, but we do not have labels for these data;train_x_small.pt- a small subset of the training set, for whose elements we do have labels;train_y_small.pt- labels for the subset of measurements contained intrain_x_small.pt;val_x.pt- measurements from the sensors that are to serve as the validation set;val_y.pt- labels for the validation set data contained inval_x.pt.
Task
Your task is:
- To train a model in self-supervised mode that learns a general representation of the training data (
train_x_big.pt) without class information; - To implement the
finetune_and_predictmethod, which trains a classifier whose inputs are the embeddings of the time series from the filetrain_x_small.pt, obtained with the self-supervised model from point one. The method must return the number of the chosen class for a given series, not its one-hot encoding.
When the solutions are tested, train_y_small.pt will have different classes from the one attached to the task. There will, however, be the same number of them. You can think of it this way: here we have the classes {"walking", "car"}, whereas during evaluation the model will be fine-tuned on the label set {"cycling", "swimming"}.
Scoring
The quality of the proposed solution will be verified by computing the accuracy on the test set, which is available only to the organisers. The test set is balanced, and the time series it contains have characteristics comparable to the validation set.
For this task you can score between 0 and 1 point. You will score 0 points if the classification accuracy on the test set is below 70%, and 1 point if it is above 90%. Between these values, the score increases linearly with the value of the criterion.
Submission files
- This notebook
- The model weights (
encoder.pt)
Constraints
The evaluation of your solution (without training, with the FINAL_EVALUATION_MODE flag set to True) should take no longer than 2 minutes on Google Colab with a T4 GPU.
Running the script on Google Colab with a GPU with the FINAL_EVALUATION_MODE flag set to False should train the model and generate the weights file in no more than 10 minutes.
The size of the encoder.pt file should not exceed 10MB.
FINAL_EVALUATION_MODE = FalseBelow, code is provided for saving and evaluating the model, as well as for loading the data. You may use it, but you do not have to.
The classes and methods below may be modified freely; you only need to remember that the finetune_and_predict() method must take four arguments (X_train_small, y_train_small, X_test, model_path)
Starter code
To begin, let us import all the necessary libraries, and define the class instances that handle the data (DataLoader), the necessary hyperparameters and a function for saving models.
import os
import random
import warnings

import gdown
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from sklearn.metrics import accuracy_score
from torch.utils.data import Dataset

warnings.filterwarnings("ignore")
# DO NOT CHANGE THESE VALUES
DEVICE = torch.device("cuda")
MODEL_FP = "./encoder.pt"# THESE VALUES MAY BE CHANGED
SEED = 42
EPOCHS = 200
N_CLASS = 6
N_CHANNEL = 3
N_LENGTH = 206
PROJECTION_DIM = 64
LOGISTIC_BATCH_SIZE = 64
LOGISTIC_EPOCHS = 10
FINETUNE_SEED = 42if not FINAL_EVALUATION_MODE:
! gdown https://drive.google.com/uc?id=1RxxsAQ6memLe4B0fePJD4cV_SIuRmhmw
# ! gdown https://drive.google.com/uc?id=1K7873pSrnIEvQe4HxhvD0S6Ur-7bEmfm
# ! gdown https://drive.google.com/uc?id=16ynUNF1WicH37L5iJszsfvVc-NJPzz8y
! unzip self_supervised.zipclass CustomTensorDataset(Dataset):
"""TensorDataset with support of transforms."""
def __init__(self, data, transform_A=None, transform_B=None):
assert all(data[0].shape[0] == item.shape[0] for item in data)
self.data = data
self.transform_A = transform_A
self.transform_B = transform_B
def __getitem__(self, index):
x = self.data[0][index]
if self.transform_A:
x1 = self.transform_A(x)
else:
x1 = x
if self.transform_B:
x2 = self.transform_B(x)
else:
x2 = x
y = self.data[1][index]
return torch.tensor(x1).float(), torch.tensor(x2).float(), torch.tensor(y)
def __len__(self):
return self.data[0].shape[0]def setup_seed(seed=42):
"""Setup seed for the reproducipility"""
torch.manual_seed(seed)
torch.cuda.manual_seed_all(seed)
np.random.seed(seed)
random.seed(seed)
torch.backends.cudnn.deterministic = TrueSolution skeleton
Models: encoder and classifier
Below, an example (and not very effective) solution to the task is implemented. It presents a simple encoder whose purpose is to create a useful representation of the data, which is later used by a simple multilayer perceptron classifier.
# Improve the class below!

class SimpleEncoder(nn.Module):
    def __init__(self, projection_dim, n_channel, n_length=240):
        super(SimpleEncoder, self).__init__()
        self.n_features = n_channel * n_length
        self.projector = nn.Sequential(
            nn.Linear(self.n_features, self.n_features // 2),
            nn.ReLU(),
            nn.Linear(self.n_features // 2, projection_dim),
        )

    def forward(self, x_i):
        h_i = x_i.flatten(start_dim=1, end_dim=-1)
        z_i = self.projector(h_i)
        return h_i, z_i

    def save_model(self, model):
        torch.save(model.state_dict(), MODEL_FP)
# Improve the class below!
class MLPClassifier(nn.Module):
def __init__(self, n_features, n_classes):
super(MLPClassifier, self).__init__()
n_dim = n_features // n_classes // 2 * n_classes
self.model = nn.Sequential(
nn.Linear(n_features, n_dim),
nn.ReLU(),
nn.Linear(n_dim, n_classes)
)
def forward(self, x):
return self.model(x)Training the encoder
If we want to train the encoder, we can use the function below. In our not very effective solution, we leave it with random weights.
# Improve the function below!

def train(unlabelled_train_loader, encoder_model):
    """Train the model (encoder) on unlabelled data."""
    optimizer = None  # TODO
    criterion = None  # TODO
    loss_epoch = []
    for epoch in range(LOGISTIC_EPOCHS):
        for step, (x_i, x_j, _) in enumerate(unlabelled_train_loader):
            optimizer.zero_grad()
            x_i = x_i.to(DEVICE)

            # TODO

            loss = criterion(...)
            loss.backward()
            optimizer.step()
            loss_epoch.append(loss.item())
    mean_loss = sum(loss_epoch) / len(loss_epoch)
    return mean_loss

if not FINAL_EVALUATION_MODE:
    X_train_big = torch.load("train_x_big.pt")
    encoder_model = SimpleEncoder(
        projection_dim=PROJECTION_DIM,
        n_channel=N_CHANNEL,
        n_length=N_LENGTH
    )

    encoder_model = encoder_model.to(DEVICE)
    encoder_model.save_model(encoder_model)
    # TODO: train(train_loader, model)
Training the classifier
# Improve the function below!

def finetune(labelled_data_loader, encoder, classifier):
    """Fine-tune the models (encoder, classifier) on labelled data."""
    optimizer = torch.optim.Adam(classifier.parameters(), lr=3e-4)
    criterion = torch.nn.CrossEntropyLoss()
    for epoch in range(LOGISTIC_EPOCHS):
        loss_epoch = []
        encoder.train()
        classifier.train()
        for n_batch, (x, x_aug, y) in enumerate(labelled_data_loader):
            optimizer.zero_grad()
            x = x.to(DEVICE)
            y = y.to(DEVICE)
            with torch.no_grad():
                h, z = encoder(x)
            output = classifier(h).to(DEVICE)
            y = y.squeeze(-1).type(torch.LongTensor).to(DEVICE)
            loss = criterion(output, y)
            loss.backward()
            optimizer.step()
            loss_epoch.append(loss.item())
        mean_loss = sum(loss_epoch) / len(loss_epoch)

    return mean_loss
The fine-tuning and prediction function
Your score will be computed using the function below. Remember to check the formal correctness of your solution with the validation script!
# Improve the function below!

def finetune_and_predict(X_train_small, y_train_small, X_test, model_path):
    """During testing we will run this function with the test data.
    Do not change the signature of this function, i.e. the number, names and order of its arguments.

    Arguments:
    X_train_small -- tensor of training data of shape (N, 1, 3, 206), where N is the number of independent measurements in the set,
    y_train_small -- vector of labels for the training set, of length N,
    X_test -- tensor of test data of shape (M, 1, 3, 206), where M is the number of independent measurements in the set,

    Return:
    The function should return a vector of length M of predicted labels for the set X_test.
    """
    setup_seed(FINETUNE_SEED)

    train_dataset = CustomTensorDataset((X_train_small, y_train_small))

    train_loader = torch.utils.data.DataLoader(
        train_dataset,
        batch_size=LOGISTIC_BATCH_SIZE,
        shuffle=True,
        drop_last=True,
    )

    encoder_model = SimpleEncoder(
        projection_dim=PROJECTION_DIM,
        n_channel=N_CHANNEL,
        n_length=N_LENGTH
    )

    encoder_model.load_state_dict(torch.load(model_path, map_location=DEVICE.type))
    encoder_model = encoder_model.to(DEVICE)
    n_classes = N_CLASS
    classifier = MLPClassifier(encoder_model.n_features, n_classes)
    classifier = classifier.to(DEVICE)
    mean_loss_train = finetune(train_loader, encoder_model, classifier)
    x = torch.tensor(X_test).to(DEVICE)
    h, z = encoder_model(x)
    output = classifier(h).to(DEVICE)
    predicted = output.argmax(1)
    assert len(predicted.shape) == 1
    assert len(predicted) == len(X_test)
    assert predicted.dtype == torch.int64
    return predicted
Evaluation
Your code will be evaluated in a way similar to the one below. Remember that in the test script all of the datasets below will be replaced: X_train_small, y_train_small and X_val alike.
X_val = torch.load("val_x.pt")
y_val = torch.load("val_y.pt")
if not FINAL_EVALUATION_MODE:
    X_train_small = torch.load("train_x_small.pt")
    y_train_small = torch.load("train_y_small.pt")
    pred = finetune_and_predict(X_train_small, y_train_small, X_val, MODEL_FP)
    print("Accuracy:", accuracy_score(y_val, pred.cpu().numpy()))
Translated by SOTA. The Polish original is the official version and wins wherever the two differ. The original task title is "Klasyfikator w dwie minuty" (A classifier in two minutes). If you organise this olympiad and would like the translation removed, email [email protected] and we will take it down.
At a glance
- You get
train_x_big.pt(unlabelled),train_x_small.ptandtrain_y_small.pt(labelled subset),val_x.ptandval_y.pt, fromself_supervised.zipon Google Drive.- You submit
- This notebook and the encoder weights
encoder.pt. - Scoring
- Accuracy on the organisers' balanced test set: 0 points below 70%, 1 point above 90%, linear in between.
- Rules
- Evaluation without training (FINAL_EVALUATION_MODE = True) must take at most 2 minutes on Google Colab with a T4 GPU.
- With FINAL_EVALUATION_MODE = False the notebook must train the model and write the weights within 10 minutes on Google Colab with a GPU.
encoder.ptmust not exceed 10 MB.- The signature of
finetune_and_predict(four arguments) must not change.
- Format
- Stage II final contest (five hours) held during the final scientific camp in Krzyżowa, 15–21 June 2024; about 30 top Stage I participants took part.